爬虫-多线程爬虫

这篇讲什么

  • 线程的两种创建方式、start() 与直接调 run() 的差别、join(timeout=) 拦不拦得住、守护线程被杀时跑不跑 finally,都有本机实测输出。
  • 数据为什么会算错:count += 1 跑 160 万次一次没丢,但把一次请求夹在读和写中间,240 次只算出 40 次——锁要圈住的是整段读-改-写。
  • 能快多少:10 个慢请求串行 3.12s、线程池 0.33s;纯计算时 4 个线程 1.52s 而 4 个进程 0.52s,这就是 GIL。
  • 两套能直接抄的实战:线程池抓公开练习站 scrape.center 的分页详情写 CSV(附单线程 / 2 / 5 / 10 线程的实测并发对照表),以及带线程安全去重与重试的版本,外加多线程下载图片的防盗链实测。
  • 线程 join/daemon、GIL 对照、锁竞态、队列生产消费、超时与重试、图片防盗链、中断与安全退出这些演示打的是本机靶站 127.0.0.1:8010:只有本机才给得了可控延迟(/slow?ms=)和可控错误码(/status/500),换成在线站就复现不出来。

线程怎么创建

官方推荐用线程池 concurrent.futures.ThreadPoolExecutor,但池子里跑的就是 threading.Thread,先把裸线程弄明白。

创建、启动、等待

thread_basic.py
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
import threading
import time

import requests

def sing(name, times):
print(f'[{threading.current_thread().name}] 收到参数 {name},唱 {times} 遍')
for _ in range(times):
time.sleep(0.05)

class DanceThread(threading.Thread):
def __init__(self, name, times):
super().__init__(name=name)
self.times = times

def run(self):
print(f'[{threading.current_thread().name}] 继承方式,run 被调用,times={self.times}')

def show_thread():
print(f' 函数体里的 current_thread().name = {threading.current_thread().name}')

def slow_http(): # 让子线程慢 800ms,好观察 join
requests.get('http://127.0.0.1:8010/slow?ms=800', timeout=5)

t1 = threading.Thread(target=sing, name='唱歌', args=('孙悟空', 2))
t2 = threading.Thread(target=sing, kwargs={'name': '猪八戒', 'times': 1})
print('启动前:t1.name =', t1.name, '| t2.name(没指定)=', t2.name, '| is_alive =', t1.is_alive())
t1.start(); t2.start()
print('启动后 is_alive =', t1.is_alive())
t1.join(); t2.join()
print('join 之后 is_alive =', t1.is_alive())
d = DanceThread('跳舞', 3); d.start(); d.join()
t = threading.Thread(target=show_thread, name='子线程甲')
t.run() # 只当函数调了一次,没开线程
print(f' run() 返回后 is_alive() = {t.is_alive()}')
t3 = threading.Thread(target=show_thread, name='子线程丙')
t3.start(); t3.join()
t = threading.Thread(target=slow_http, name='慢请求')
t0 = time.time()
t.start()
t.join(0.3)
print(f' join(0.3) 返回,耗时 {time.time() - t0:.2f}s,此时 is_alive() = {t.is_alive()}')
t.join()
print(f' join() 无参返回,总耗时 {time.time() - t0:.2f}s,is_alive() = {t.is_alive()}')
1
2
3
4
5
6
7
8
9
启动前:t1.name = 唱歌 | t2.name(没指定)= Thread-1 (sing) | is_alive = False
启动后 is_alive = True
join 之后 is_alive = False
[跳舞] 继承方式,run 被调用,times=3
函数体里的 current_thread().name = MainThread
run() 返回后 is_alive() = False
函数体里的 current_thread().name = 子线程丙
join(0.3) 返回,耗时 0.31s,此时 is_alive() = True
join() 无参返回,总耗时 0.82s,is_alive() = False
  • 三个常用参数:target、args / kwargs、name;不写 name 时自动编号成 Thread-1 (sing),括号里带函数名。继承 Thread 时记得手动 super().__init__(name=name),并且只覆写 run,别覆写 start。查岗用 current_thread()、active_count()(含主线程,3 个工人时实测 4)和 enumerate()(实测 ['MainThread', '工人0', '工人1', '工人2'])。
  • 直接 t.run() 就是普通调用:线程名还是 MainThread、is_alive() 一直是 False,而且 run() 结尾会把 _target 删掉,这个对象再 start() 就废了,实测抛 AttributeError: 'Thread' object has no attribute '_target'。join() 是「主线程在这里等子线程结束」,不是「让子线程结束」;join(timeout) 到点就返回,不管线程活没活完(0.31s 时那个 800ms 的请求还在跑),所以要自己看 is_alive();对没 start() 的线程调 join() 会报 RuntimeError: cannot join thread before it is started。

daemon:主线程走了它就死

daemon_demo.py
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
import subprocess
import sys

CHILD = """
import sys
import threading
import time


def heartbeat(times):
try:
for i in range(1, times + 1):
print(f' 第 {i} 次心跳', flush=True)
time.sleep(0.2)
finally:
print(' finally 执行了', flush=True)


daemon = sys.argv[1] == 'true'
print(f' [{("daemon" if daemon else "nondaemon")}] 主线程只睡 0.5s,t.daemon = {daemon}')
t = threading.Thread(target=heartbeat, args=(5,), daemon=daemon)
t.start()
time.sleep(0.5)
print(' 主线程代码跑完了,进程该退了', flush=True)
"""

for flag in ('true', 'false'): # 各开一个进程,否则前一个守护线程会活到进程结束
out = subprocess.run([sys.executable, '-X', 'utf8', '-c', CHILD, flag],
capture_output=True, text=True, encoding='utf-8')
print(out.stdout.rstrip())
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
[daemon] 主线程只睡 0.5s,t.daemon = True
第 1 次心跳
第 2 次心跳
第 3 次心跳
主线程代码跑完了,用了 0.50s
[nondaemon] 主线程只睡 0.5s,t.daemon = False
第 1 次心跳
第 4 次心跳
第 2 次心跳
第 5 次心跳
第 3 次心跳
主线程代码跑完了,用了 0.50s
finally 执行了
第 4 次心跳
第 5 次心跳
finally 执行了
[nondaemon] join() 回来才真退出,总耗时 1.00s
  • 子线程每 0.2s 打一次心跳、共 5 次(heartbeat 里 try 包着循环、finally 打一行收尾),主线程只睡 0.5s 就退出;daemon=True 与 daemon=False 各跑一遍就是上面的差别:守护版心跳停在第 3 次、finally 根本没跑,非守护版主线程退完了进程还要等它跳满 5 次才执行 finally,两遍总耗时实测 0.54s 与 1.05s。
  • daemon 只能在构造时给(或 start() 之前设),所以守护线程里别放收尾工作:实测在守护线程里开文件写 8 行、每行 sleep(0.15),主线程 0.3s 退出后文件是空的(wc -l 得 0 行)——没 close(),缓冲区里的内容跟着进程一起没了。

线程间要同步

不加锁真的会算错

counter_race.py
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
import threading
import time

import requests

BASE = 'http://127.0.0.1:8010'
lock = threading.Lock()

def bump(box):
for _ in range(200_000):
box['n'] += 1 # 纯 count += 1,没有让出 GIL 的机会

def rmw_http(box, mode='none'):
s = requests.Session()
for _ in range(40):
if mode == 'full': # 读、请求、写回整段都在锁里
with lock:
cur = box['n']
s.get(BASE + '/list', timeout=5)
box['n'] = cur + 1
else:
cur = box['n'] # 1. 读
s.get(BASE + '/list', timeout=5) # 2. 发请求时让出了 GIL
if mode == 'write':
with lock: # 只锁住写回这一步
box['n'] = cur + 1
else:
box['n'] = cur + 1 # 3. 把旧值写回去

def show(label, target, expect, n, *args):
box = {'n': 0}
ts = [threading.Thread(target=target, args=(box,) + args) for _ in range(n)]
t0 = time.time()
for t in ts: t.start()
for t in ts: t.join()
print(f' {label}:期望 {expect},实测 {box["n"]},丢 {expect - box["n"]},耗时 {time.time() - t0:.2f}s')

show('纯 count += 1 ', bump, 1600000, 8)
show('读-请求-写(无锁) ', rmw_http, 240, 6)
show('读-请求-写(只锁写) ', rmw_http, 240, 6, 'write')
show('读-请求-写(整段锁) ', rmw_http, 240, 6, 'full')
1
2
3
4
纯 count += 1        :期望 1600000,实测 1600000,丢 0,耗时 0.12s
读-请求-写(无锁) :期望 240,实测 40,丢 200,耗时 0.14s
读-请求-写(只锁写) :期望 240,实测 41,丢 199,耗时 0.13s
读-请求-写(整段锁) :期望 240,实测 240,丢 0,耗时 0.27s
  • 第一行看着反直觉:8 线程各 20 万次 += 1 一次没丢。因为 CPython 的切换检查点很稀疏,这一圈里没有让出 GIL 的机会——不是没有竞态,是没撞上(把 time.sleep(0) 夹在读和写中间,同一份代码 18 万次就只数出 30418,丢 149582)。
  • 只要读和写之间夹了会阻塞的东西(这里就是打本机靶站 /list 的一次请求,真实爬虫里是一次网络往返),窗口立刻打开:240 次只数出 40 次。只锁写回完全没用:错的值早就读进来了,锁只是给「写回错误值」排队;整段都锁住值才对了,代价是 0.14s → 0.27s,请求全串行了。所以实操原则是:能不放进锁的绝对不放,最好干脆别共享——结果 return 出去或塞进队列,最后主线程汇总,下文实战就这么写。

锁与同步原语

sync_primitives.py
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
import threading
import time

lock = threading.Lock()
lock.acquire()
print(' 同一线程第二次 acquire(timeout=0.3) =', lock.acquire(timeout=0.3))
lock.release()

rlock, t0 = threading.RLock(), time.time()


def worker():
with rlock: # 主线程还握着锁,这里只能等
print(' %.1fs [工人] 我进来了' % (time.time() - t0))


with rlock:
with rlock: # 同一个线程嵌套进入没问题
print(' %.1fs [MainThread] 主线程嵌套第二次进入,没卡住' % (time.time() - t0))
w = threading.Thread(target=worker)
w.start()
time.sleep(0.4) # 出最外层 with 之前,锁一直握着
w.join()

sem, guard, state = threading.Semaphore(3), threading.Lock(), [0, 0]


def job():
with sem:
with guard:
state[0] += 1
state[1] = max(state[1], state[0])
time.sleep(0.2)
with guard:
state[0] -= 1


t1 = time.time()
ts = [threading.Thread(target=job) for _ in range(10)]
for t in ts: t.start()
for t in ts: t.join()
print(' Semaphore(3):同时在跑的最大数量 = %d,总耗时 %.1fs' % (state[1], time.time() - t1))

bounded = threading.BoundedSemaphore(1)
bounded.acquire()
bounded.release()
try:
bounded.release()
except ValueError as e:
print(' BoundedSemaphore 多 release:ValueError: %s' % e)

ev, t2 = threading.Event(), time.time()
print(' 没人 set 时 wait(0.5) 返回 %s,等了 %.1fs' % (ev.wait(0.5), time.time() - t2))

cond = threading.Condition()
with cond:
print(' 没人在 wait 时 notify() 返回', cond.notify())

timer = threading.Timer(30, lambda: None)
print(' Timer 是线程吗:isinstance = %s,daemon = %s' % (
isinstance(timer, threading.Thread), timer.daemon))
timer.cancel()
1
2
3
4
5
6
7
8
同一线程第二次 acquire(timeout=0.3) = False
0.0s [MainThread] 主线程嵌套第二次进入,没卡住
0.4s [工人] 我进来了
Semaphore(3):同时在跑的最大数量 = 3,总耗时 0.8s
BoundedSemaphore 多 release:ValueError: Semaphore released too many times
没人 set 时 wait(0.5) 返回 False,等了 0.5s
没人在 wait 时 notify() 返回 None
Timer 是线程吗:isinstance = True ,daemon = False
  • Lock 不可重入:同一线程第二次 acquire() 就是自锁,带 timeout=0.3 返回 False,不写 timeout 就永久卡死、连报错都没有;它也不记数,多 release() 直接 RuntimeError: release unlocked lock。所以一律写 with lock:,异常时也会自动释放。RLock 才让同一线程嵌套进入(主线程持有后第二次照样进),代价是别的线程得等它把递归全退完:工人 0.00s 就想进来,直到 0.40s 才拿到锁。
  • Semaphore(n) 是闸门:10 个任务、闸门 3,实测同时在跑的最多 3 个,0.81s 就是 4 轮 × 0.2s。普通 Semaphore 多 release() 不报错,计数从 1 变 2、闸门等于被你放开,BoundedSemaphore 会拦下来;ThreadPoolExecutor(max_workers=3) 已经把「池 + 闸门」打包好了。
  • Event 是个开关:set() 后所有在等的线程一起走,没人 set 时 wait(0.5) 等满 0.51s 返回 False,爬虫里拿它当「停止信号」最顺手。Condition 是锁加叫醒机制,wait() 先让出锁再睡、被 notify() 叫醒后拿到生产者放的「一页 HTML」,没人等时 notify() 不补发(实测返回 None)。Timer 本身就是线程且默认非守护,cancel() 只在没到点时有效。

队列 queue

下载线程和解析线程之间别共享列表,用 queue.Queue:它内部把锁做好了,put / get 天生线程安全。

put、get 与 task_done

queue_basic.py
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
import queue
import threading
import time

q = queue.Queue(2)
q.put('a')
q.put('b')
print(' put 满之后 qsize() = %d,full() = %s,maxsize = %d' % (q.qsize(), q.full(), q.maxsize))

def drainer():
time.sleep(0.4)
q.get()

threading.Thread(target=drainer).start()
t0 = time.time()
q.put('c') # 队列是满的,只能等有人取走
print(' 阻塞的 put 在有人取走后返回了,等了 %.1fs' % (time.time() - t0))

empty_q, t1 = queue.Queue(), time.time()
try:
empty_q.get(timeout=0.5)
except queue.Empty:
print(' get(timeout=0.5) 等了 %.1fs 抛 Empty' % (time.time() - t1))

q4 = queue.Queue()
for i in range(3):
q4.put(i)
print(' 放进 3 个,未完成数 unfinished_tasks =', q4.unfinished_tasks)

def worker():
while True:
try:
item = q4.get(timeout=0.5)
except queue.Empty:
return
time.sleep(0.2)
q4.task_done()

t2 = time.time()
w = threading.Thread(target=worker)
w.start()
q4.join() # 等的是三个项都被 task_done 确认过
print(' q4.join() 返回,耗时 %.1fs' % (time.time() - t2))
w.join()

try:
q4.task_done()
except ValueError as e:
print(' 多 task_done 一次:ValueError: %s' % e)
1
2
3
4
5
6
put 满之后 qsize() = 2,full() = True,maxsize = 2
阻塞的 put 在有人取走后返回了,等了 0.40s
get(timeout=0.5) 等了 0.51s 抛 Empty
放进 3 个,未完成数 unfinished_tasks = 3
q4.join() 返回,耗时 0.60s
多 task_done 一次:ValueError: task_done() called too many times
  • Queue(maxsize) 满了再 put 就等:put(block=False) 立刻抛 queue.Full,put(timeout=0.5) 等 0.51s 抛 Full,等有别的线程 get() 走了一个才在 0.40s 后返回;Queue(0) 是无限长,爬虫里一定要设上限,否则下载快过解析时内存一路涨。get 默认一直等,get_nowait() 立刻抛 Empty,get(timeout=0.5) 等满 0.51s 抛 Empty。
  • 队列的 join() 等的是「每个取出去的项都被 task_done() 确认过」(unfinished_tasks 从 3 归零),不是等队列变空:一个 get() 配一个 task_done(),task_done() 多了报 ValueError,少了 join() 永远醒不过来;3 项 × 0.2s 正好 0.60s。
  • qsize() / unfinished_tasks 官方文档写明在多线程下只是近似值,不能当判据:实测队列里放 1 个项、3 个线程同时抢,三个线程读到的 qsize() 分别是 1、0、0,只有一个真拿到,另两个立刻 Empty。所以别写 while not q.empty(): q.get(),要用 get(timeout=) 配 try/except Empty,或者放哨兵(塞个 None 表示收工)。

三种变形队列

queue_variants.py
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
import queue

lifo = queue.LifoQueue()
for n in (1, 2, 3):
lifo.put(n)
print(' LifoQueue 取出来:%s' % [lifo.get() for _ in range(3)])

prio = queue.PriorityQueue()
for item in [(2, '普通的'), (1, 'B站'), (3, '慢慢来的'), (1, 'A站'), (1, '紧急的')]:
prio.put(item)
print(' PriorityQueue 取出来:%s' % [prio.get() for _ in range(5)])

simple = queue.SimpleQueue()
simple.put('x')
print(' SimpleQueue.get() = %s,empty() = %s' % (simple.get(), simple.empty()))
try:
simple.task_done()
except AttributeError as e:
print(' SimpleQueue 没有 task_done:AttributeError: %s' % e)

mixed = queue.PriorityQueue()
try: # 堆是在 put 的时候就比较了
mixed.put(('字符串', 1))
mixed.put((2, '数字'))
except TypeError as e:
print(' 不同类型放一起:TypeError: %s' % e)
1
2
3
4
LifoQueue 取出来: [3, 2, 1]
PriorityQueue 取出来: [(1, 'A站'), (1, 'B站'), (1, '紧急的'), (2, '普通的'), (3, '慢慢来的')]
SimpleQueue.get() = x ,empty() = True
SimpleQueue 没有 task_done:AttributeError: '_queue.SimpleQueue' object has no attribute 'task_done'
  • LifoQueue 是栈,先入后出,做深度优先的链接追踪正合适;PriorityQueue 按元组第一个元素排,第一个相同就继续比第二个,所以 (优先级, 序号, url) 最稳,别让 URL 自己去比大小,元素类型混了直接 TypeError;SimpleQueue 更快,但不能限长、没有 task_done(配合不了 join()),爬虫里一般还是用 Queue。

生产者-消费者抓分页

producer_worker.py
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
def down(page_q, html_q):                  # 2 个下载线程干这个
while True:
try:
url = page_q.get(timeout=0.5)
except Empty:
return # 0.5s 取不到就收工
try:
html_q.put((url, requests.get(url, timeout=10).text))
finally:
page_q.task_done() # 一个 get 配一个 task_done

def parse(name, html_q, fp, stats): # 2 个解析线程干这个,形状对称
while True:
try:
url, html = html_q.get(timeout=0.5)
except Empty:
return
items = BeautifulSoup(html, 'lxml').select('#books li.item')
with write_lock: # 写文件和统计只有这一处在动
for li in items:
row = {'page': url.rsplit('=', 1)[1], 'id': li['data-id'],
'title': li.select_one('a.title').get_text(strip=True)}
fp.write(json.dumps(row, ensure_ascii=False) + '\n')
stats['pages'] += 1
stats['items'] += len(items)
print(f' [{name}] {url} 解析出 {len(items)} 条', flush=True)
html_q.task_done()

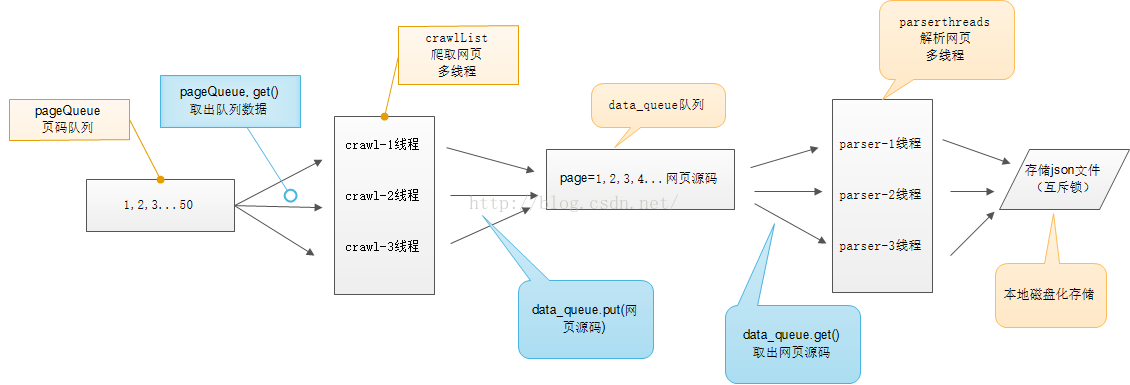
主线程把 page_q、html_q 都建成 Queue(maxsize=4) / Queue(maxsize=8),塞 4 个页码(其中一页重复),起 2 + 2 个线程,先 join 下载线程,再 page_q.join()、html_q.join() 等两条队列都确认完,实测:

1
2
3
4
5
  [解析0] http://127.0.0.1:8010/list?page=1 解析出 3 条
[解析1] http://127.0.0.1:8010/list?page=2 解析出 1 条
跑了 0.65s,pages=4,items=8

8 producer_items.jsonl
  • 结构就三样:待抓 URL 队列、结果队列、写文件时的一把锁;下载线程只管塞、解析线程只管取,谁都不用自己判空。这里喂给队列的是本机靶站的 /list?page=,只把它当一路有固定延迟的输入源,重点在队列机制不在站点。两个队列都设了 maxsize,下载跑太快会自己停下来等解析,这就是「背压」,比无脑堆内存健康;4 个页码里有一对重复,队列不做去重,所以同一页被抓了两遍、落盘 8 行,去重要自己来(实战那节就做)。

GIL 与真实收益

I/O 用线程,计算用进程

bench.py
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
import os
import sys
import threading
import time
from concurrent.futures import ProcessPoolExecutor, ThreadPoolExecutor

import requests

URL = 'http://127.0.0.1:8010/slow?ms=300'
CHUNK = 6_000_000

def one(url):
return requests.get(url, timeout=10).json()['slept_ms']

def heavy(n):
total = 0
for i in range(n):
total += i * i
return total

def timed(name, fn):
t0 = time.time()
fn()
print(f' {name}:耗时 {time.time() - t0:.2f}s')

def four_threads():
ts = [threading.Thread(target=heavy, args=(CHUNK,)) for _ in range(4)]
for t in ts: t.start()
for t in ts: t.join()

if __name__ == '__main__':
timed('串行 for 循环 10 次 ', lambda: [one(URL) for _ in range(10)])
timed('ThreadPoolExecutor(max_workers=3) ', lambda: list(ThreadPoolExecutor(3).map(one, [URL] * 10)))
timed('ThreadPoolExecutor(max_workers=10)', lambda: list(ThreadPoolExecutor(10).map(one, [URL] * 10)))
timed('ThreadPoolExecutor(max_workers=20)', lambda: list(ThreadPoolExecutor(20).map(one, [URL] * 10)))
print(f' Python {sys.version.split()[0]},os.cpu_count() = {os.cpu_count()},GIL 开着吗 sys._is_gil_enabled() = {sys._is_gil_enabled()}')
timed('主线程串行跑 4 段 ', lambda: [heavy(CHUNK) for _ in range(4)])
timed('4 个线程同时跑 4 段 ', four_threads)
timed('ThreadPoolExecutor(4) ', lambda: list(ThreadPoolExecutor(4).map(heavy, [CHUNK] * 4)))
timed('ProcessPoolExecutor(4) ', lambda: list(ProcessPoolExecutor(4).map(heavy, [CHUNK] * 4)))
1
2
3
4
5
6
7
8
9
串行 for 循环 10 次           :耗时 3.12s
ThreadPoolExecutor(max_workers=3) :耗时 1.22s
ThreadPoolExecutor(max_workers=10):耗时 0.33s
ThreadPoolExecutor(max_workers=20):耗时 0.32s
Python 3.14.10,os.cpu_count() = 20,GIL 开着吗 sys._is_gil_enabled() = True
主线程串行跑 4 段 :耗时 1.45s
4 个线程同时跑 4 段 :耗时 1.52s
ThreadPoolExecutor(4) :耗时 1.49s
ProcessPoolExecutor(4) :耗时 0.52s
  • 这一段的 I/O 基准打的是本机靶站的固定延迟端点 /slow?ms=300:每个请求服务端都要睡满 300ms,串行就是 10 × 0.3 ≈ 3.1s;开 10 个线程 0.33s,接近 10 倍。换成在线站就没有这种可控延迟,数字也复现不出来,所以对照留在靶站。原理是 requests.get 等网络时阻塞在系统调用上,会把 GIL 交出来,别的线程于是能接着发自己的请求——这就是爬虫靠线程提速的全部原理。
  • GIL(全局解释器锁)让同一时刻只有一个线程在执行 Python 字节码,所以纯计算的 4 个线程不但没快,还慢了一点(1.45 → 1.52)。换成进程才是多份 GIL、多份解释器,4 个进程 0.52s,约 2.8 倍;代价是进程间只能传可序列化对象、起进程也贵:本机 2 进程 0.88s、4 进程 0.53s、8 进程 0.51s,任务只有 4 段时再多进程也榨不出油水。结论:抓页面是 I/O 密集,线程够用;只有解析特别重(大正则回溯、图片识别)才值得上进程。

max_workers 不是越大越好

同一批 30 个 ssr1 详情页(/detail/1 ~ /detail/30,每轮带一个 _=轮次 查询参数绕开 CDN 缓存,保证每次都回源),单线程和 2 线程各跑 1 轮,5、10 线程各跑 2 轮取中位数。原始输出:

workers_bench.py
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
import statistics
import time
from concurrent.futures import ThreadPoolExecutor

import requests

BASE = 'https://ssr1.scrape.center'
PLAN = [(1, 1), (2, 1), (5, 2), (10, 2)] # (线程数, 跑几轮)

def one(url):
t0 = time.perf_counter()
for attempt in range(3): # 抖一下就重试,最多两次
try:
r = requests.get(url, timeout=15)
r.raise_for_status()
return time.perf_counter() - t0, attempt
except requests.RequestException:
if attempt == 2:
raise

for workers, rounds in PLAN:
for r in range(1, rounds + 1):
# 每轮带一个 _=轮次 参数绕开 CDN 缓存,保证每次都回源
urls = ['%s/detail/%d?_=%d%d' % (BASE, i, workers, r) for i in range(1, 31)]
t0 = time.perf_counter()
with ThreadPoolExecutor(max_workers=workers) as ex:
result = list(ex.map(one, urls))
total = time.perf_counter() - t0
lat = sorted(x[0] for x in result)
retried = sum(x[1] > 0 for x in result)
print(' workers=%-2d r%d-%d:总耗时 %5.2fs 成功 %d/30 重试 %d 次 '
'单请求延迟 中位 %.2fs 最快 %.2fs 最慢 %.2fs' % (
workers, workers, r, total, len(result) - retried, retried,
statistics.median(lat), lat[0], lat[-1]))
1
2
3
4
5
6
workers=1   r1-1:总耗时  29.97s  成功 30/30  重试 0 次  单请求延迟 中位 0.85s  最快 0.49s  最慢 3.09s
workers=2 r2-1:总耗时 17.55s 成功 30/30 重试 0 次 单请求延迟 中位 1.04s 最快 0.52s 最慢 2.44s
workers=5 r5-1:总耗时 10.11s 成功 30/30 重试 0 次 单请求延迟 中位 1.28s 最快 0.70s 最慢 3.83s
workers=5 r5-2:总耗时 8.63s 成功 30/30 重试 0 次 单请求延迟 中位 1.25s 最快 0.61s 最慢 2.67s
workers=10 r10-1:总耗时 10.21s 成功 30/30 重试 0 次 单请求延迟 中位 2.30s 最快 0.94s 最慢 5.66s
workers=10 r10-2:总耗时 8.41s 成功 30/30 重试 0 次 单请求延迟 中位 2.18s 最快 1.15s 最慢 5.34s
并发线程 中位耗时 加速比 失败/重试
单线程 29.97s 1.00x 0 次
2 线程 17.55s 1.71x 0 次
5 线程 9.37s 3.20x 0 次
10 线程 9.31s 3.22x 0 次
  • 加速比是拿单线程那轮做分母。单线程到 5 线程是真金白银的提速(1.00x → 1.71x → 3.20x):抓详情页几乎全卡在等网络,多开线程就是把这些等待叠起来。
  • 真正的拐点在 5 → 10:中位耗时 9.37s → 9.31s、加速比 3.20x → 3.22x,几乎原地踏步;可同一批请求的单请求延迟中位数却从 1.28s 涨到 2.30s、最慢一次冲到 5.66s。线程堆得越多,站点那边每个请求排得越久,总时长不降反微升——5 线程已经摸到这台站点的吞吐上限,再加只是把延迟摊薄、白白多开线程。全程 30/30 成功、0 次重试,scrape.center 也不封这个并发度。
  • 不写 max_workers 时按 min(32, cpu_count + 4) 算:本机 20 核 → 24(实测默认池就是 24);默认线程名是 ThreadPoolExecutor-0_0 这种,建议用 thread_name_prefix='detail' 换个好认的。对这类在线练习站,一般 4~10 就够,宁可稳一点。
  • 还要留一层风险:换回本机靶站短时间连续高压跑几轮,一个请求一条新连接、TIME_WAIT 堆满就能把本机临时端口耗光,真实站点上则多半是封 IP:
port_exhausted.py
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
import socket

import requests

BASE = 'http://127.0.0.1:8010'
PORT = 47213 # 真实场景是 TIME_WAIT 占满整段临时端口,这里先占住一个
keeper = socket.socket()
keeper.bind(('127.0.0.1', PORT))

class Pinned(requests.adapters.HTTPAdapter):
"""逼着 requests 只用这个源端口出连接,等于系统给不出可用的临时端口。"""

def init_poolmanager(self, *args, **kwargs):
kwargs['source_address'] = ('127.0.0.1', PORT)
return super().init_poolmanager(*args, **kwargs)

print(' 源端口没人占时正常请求:', requests.get(BASE + '/list', timeout=5).status_code)
s = requests.Session()
s.mount('http://', Pinned())
try:
s.get(BASE + '/list', timeout=5)
except requests.exceptions.ConnectionError as e:
print('%s.%s: %s' % (type(e).__module__, type(e).__name__, e))
keeper.close()
s2 = requests.Session()
s2.mount('http://', Pinned())
print(' 释放端口后同一个地址再来一次:', s2.get(BASE + '/list', timeout=5).status_code)
1
requests.exceptions.ConnectionError: HTTPConnectionPool(host='127.0.0.1', port=8010): Max retries exceeded with url: /list (Caused by NewConnectionError("HTTPConnection(host='127.0.0.1', port=8010): Failed to establish a new connection: [WinError 10048] 通常每个套接字地址(协议/网络地址/端口)只允许使用一次。"))

Session 别跨线程共用

session_reuse.py
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
import threading
import time

import requests

BASE = 'http://127.0.0.1:8010'
N = 40

new_conn, reused = [], []
for _ in range(3): # 各测三遍,取最快的一遍
t0 = time.perf_counter()
for _ in range(N):
requests.get(BASE + '/list', timeout=5) # 每次新建连接
new_conn.append(time.perf_counter() - t0)
session = requests.Session()
session.get(BASE + '/list', timeout=5) # 先把那条连接建好
t1 = time.perf_counter()
for _ in range(N):
session.get(BASE + '/list', timeout=5) # 复用一个 Session
reused.append(time.perf_counter() - t1)
print(' 串行 %d 次:每次新建连接 %.2fs,复用一个 Session %.2fs' % (N, min(new_conn), min(reused)))

def cookie_case(make_session, label):
"""10 个线程各自先发 /cookies 拿到自己的 sid,齐了以后再一起发 /readcookie。"""
barrier, lock, mine, wrong = threading.Barrier(10), threading.Lock(), [], []

def one():
sess = make_session()
raw = sess.get(BASE + '/cookies', timeout=10).headers['Set-Cookie']
own = raw.split('=')[1].split(';')[0]
barrier.wait()
back = sess.get(BASE + '/readcookie', timeout=10).json()['sid']
with lock:
mine.append(own)
if back != own:
wrong.append(own)

ts = [threading.Thread(target=one) for _ in range(10)]
for t in ts: t.start()
for t in ts: t.join()
print(' 10 个线程%s:%d 个读回来的 sid 不是自己刚拿到的那个,读回来的一共 %d 种'
% (label, len(wrong), len(set(mine))))

shared = requests.Session()
cookie_case(lambda: shared, '共用 1 个 Session')

local = threading.local()

def per_thread_session(): # 正解:一线程一个 Session
if not hasattr(local, 's'):
local.s = requests.Session()
return local.s

cookie_case(per_thread_session, '各用各的 Session')
1
2
3
4
串行 40 次:每次新建连接 0.50s,复用一个 Session 0.04s
10 个线程共用 1 个 Session:9 个读回来的 sid 不是自己刚拿到的那个
我以为是我的 f5394a97,服务器这次带的是 31ed328b
我以为是我的 83f78edc,服务器这次带的是 31ed328b
  • 复用连接省掉重建连接和 cookie 往来的开销,实测 40 次请求 0.50s → 0.04s,所以单线程也该用 Session。但上面第二组(10 个线程共用一个,打的是本机靶站的 /cookies、/readcookie:各自先拿一个新 sid、睡 0.05s 再读回来)里 9 个线程读到的不是自己刚拿到的那个——官方文档说得很明确,Session 不是线程安全的。
  • 正解是一线程一个 Session,用 threading.local() 存(同样的用例实测 0 个读错),写法就是下文实战里的 get_session()。

多线程爬虫实战

抓页面、抽数据的实战都走公开练习站 scrape.center——它是《Python3 网络爬虫开发实战》作者搭的、专门给爬虫练手的站点,服务端渲染,requests 直接就能拿到带数据的 HTML,而且不校验 UA/Referer,同一 IP 连发也不封。下面这份从 10 个列表页取回 100 个详情链接,再用线程池抓详情、解析成 CSV。

线程池抓分页详情

pool_spider.py
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
import csv
import threading
import time
from concurrent.futures import ThreadPoolExecutor, as_completed

import requests
from bs4 import BeautifulSoup

BASE = 'https://ssr1.scrape.center'
local = threading.local()

def get_session(): # 一线程一个 Session,别跨线程共用
if not hasattr(local, 's'):
local.s = requests.Session()
return local.s

def fetch(url):
r = get_session().get(url, timeout=15)
r.raise_for_status()
return r.text

def parse_detail(url): # 详情页取名称 / 评分 / 地区时长 / 上映日期
soup = BeautifulSoup(fetch(url), 'lxml')
infos = [d.get_text(' ', strip=True) for d in soup.select('div.info')]
return {'id': int(url.rsplit('/', 1)[1]), 'name': soup.select_one('h2').get_text(strip=True),
'score': soup.select_one('[class*=score]').get_text(strip=True),
'region_time': infos[0], 'released': infos[1].replace(' 上映', '')}

t0 = time.time()
detail_urls = []
with ThreadPoolExecutor(max_workers=5, thread_name_prefix='list') as ex:
futures = {ex.submit(fetch, f'{BASE}/page/{p}'): p for p in range(1, 11)}
for fut in as_completed(futures):
hrefs = [a['href'] for a in BeautifulSoup(fut.result(), 'lxml').select('a.name')]
detail_urls.extend(BASE + href for href in hrefs)
print(f' 列表页 10 个,拿到 {len(detail_urls)} 个详情链接({time.time() - t0:.2f}s)')

rows = []
with ThreadPoolExecutor(max_workers=8, thread_name_prefix='detail') as ex:
futures = {ex.submit(parse_detail, u): u for u in detail_urls}
for fut in as_completed(futures):
try:
rows.append(fut.result())
except requests.RequestException as e:
print(f' {futures[fut]} 抓取失败:{type(e).__name__}: {e}')

rows.sort(key=lambda r: r['id'])
print(f' 抓到 {len(rows)} 条记录,耗时 {time.time() - t0:.2f}s')
with open('movies.csv', 'w', newline='', encoding='utf-8-sig') as f:
w = csv.DictWriter(f, fieldnames=['id', 'name', 'score', 'region_time', 'released'])
w.writeheader(); w.writerows(rows)
print(' 已写 movies.csv')
for r in rows[:5]:
print(f" #{r['id']:<3} {r['name']} | {r['score']} | {r['region_time']} | {r['released']}")
1
2
3
4
5
6
7
8
列表页 10 个,拿到 100 个详情链接(1.45s)
抓到 100 条记录,耗时 28.08s
已写 movies.csv
#1 霸王别姬 - Farewell My Concubine | 9.5 | 中国内地、中国香港 / 171 分钟 | 1993-07-26
#2 这个杀手不太冷 - Léon | 9.5 | 法国 / 110 分钟 | 1994-09-14
#3 肖申克的救赎 - The Shawshank Redemption | 9.5 | 美国 / 142 分钟 | 1994-09-10
#4 泰坦尼克号 - Titanic | 9.5 | 美国 / 194 分钟 | 1998-04-03
#5 罗马假日 - Roman Holiday | 9.5 | 美国 / 118 分钟 | 1953-08-20
  • submit 返回 Future,用字典把 future 和页码/URL 绑起来,as_completed 是谁先回来先处理,不用干等最慢的那个。结果只在主线程汇总(任务只 return 一个 dict),全程不共享可变对象,比到处加锁省事又不会算错;落盘前 rows.sort(),因为并发回来的顺序是乱的。给 Excel 看要用 encoding='utf-8-sig'。
  • 这个站的稳定边界得实测才知道:列表页最多翻到 /page/10,/page/11 实测直接 500;详情页 id 看着能到 108,但 /detail/101 实测就是 500,照着列表页给的链接抓才稳,别按 id 递增硬扫。至于这段该开几个线程,看前文「max_workers 不是越大越好」那张实测表——这批详情页上 5 线程就到顶了。
  • 别拿这段的秒数当基准:同一段代码我隔十几分钟又跑了一次,列表页 1.45 秒变成 9.03 秒、100 条详情 28.08 秒变成 19.08 秒。列表页那层是 CDN 缓存在起作用(ssr1 的响应头带 Cache-Control: max-age=600),命中时飞快、过期回源就慢;详情页大小差一个数量级,耗时主要看命中的是哪几部。所以并发实验要么像上一节那样加 _=轮次 强制回源,要么多跑几轮取中位数,单次数字只说明「能跑通」,不说明快慢。

多线程爬取流程

线程安全的去重与重试

超时和重试的对照需要「一定超时、一定 5xx」的端点,在线练习站给不了这种可控失败,所以这一段打回本机靶站 127.0.0.1:8010 的 /status/500、/slow?ms=3000:去重和重试的机制照样成立,只是把可控的失败源摆到本机。

safe_spider.py
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
import threading
import time
from concurrent.futures import ThreadPoolExecutor, as_completed

import requests

BASE = 'http://127.0.0.1:8010'

class UrlSet:
def __init__(self):
self._seen = set()
self._lock = threading.Lock()
def add_if_new(self, url):
with self._lock: # 查和登记在一把锁里做完
if url in self._seen:
return False
self._seen.add(url)
return True

def fetch(url, timeouts=(5, 5, 8)): # get_session() 见上一节:一线程一个 Session
last_exc = None
for attempt, timeout in enumerate(timeouts, 1):
try:
r = get_session().get(url, timeout=timeout)
if r.status_code >= 500:
raise requests.HTTPError(f'服务端返回 {r.status_code}', response=r)
r.raise_for_status()
if attempt > 1:
print(f' {url} 第 {attempt} 次重试成功', flush=True)
return r
except (requests.ConnectionError, requests.Timeout, requests.HTTPError) as e:
last_exc = e
print(f' {url} 第 {attempt} 次失败:{type(e).__name__}: {e} -> {0.2 * attempt:.1f}s 后重试', flush=True)
time.sleep(0.2 * attempt)
raise last_exc

t0 = time.time()
urls = UrlSet()
seeds = [f'{BASE}/list?page={p}' for p in (1, 2)] + [f'{BASE}/list?page=1']
specials = {f'{BASE}/status/500': (5, 5, 8), f'{BASE}/slow?ms=3000': (2, 5, 8)}
with ThreadPoolExecutor(max_workers=6, thread_name_prefix='detail') as ex:
futures = {ex.submit(fetch, u): u for u in seeds if urls.add_if_new(u)}
print(f' 种子 {len(seeds)} 个 URL,去重后真正发出去的 {len(futures)} 个')
for fut in as_completed(futures):
print(f' {futures[fut]} -> {fut.result().status_code}', flush=True)
futures = {ex.submit(fetch, u, to): u for u, to in specials.items()}
for fut in as_completed(futures):
try:
print(f' {futures[fut]} 最终 {fut.result().status_code}', flush=True)
except Exception as e:
print(f' 放弃 {futures[fut]} —— {type(e).__name__}: {e}', flush=True)
print(f' 累计耗时 {time.time() - t0:.2f}s,去重容器里有 {len(urls)} 个 URL')
1
2
3
4
5
6
7
8
种子 3 个 URL,去重后真正发出去的 2 个
http://127.0.0.1:8010/status/500 第 1 次失败:HTTPError: 服务端返回 500 -> 0.2s 后重试
http://127.0.0.1:8010/status/500 第 3 次失败:HTTPError: 服务端返回 500 -> 0.6s 后重试
放弃 http://127.0.0.1:8010/status/500 —— HTTPError: 服务端返回 500
http://127.0.0.1:8010/slow?ms=3000 第 1 次失败:ReadTimeout: HTTPConnectionPool(host='127.0.0.1', port=8010): Read timed out. (read timeout=2) -> 0.2s 后重试
http://127.0.0.1:8010/slow?ms=3000 第 2 次重试成功
http://127.0.0.1:8010/slow?ms=3000 最终 200
累计耗时 5.36s,去重容器里有 2 个 URL
  • add_if_new() 把查和登记放同一把锁里,是因为「先查后加」会重复干活:实测 8 个线程对同一批 URL 跑 if u not in seen: seen.add(u),seen 里确实是 4 条,但实际抓了 6 次(同一个 URL 被抓了 3 遍)。
  • 重试只对「抖得过去」的错误有用:慢接口第一次只给 2s 超时(ReadTimeout),第二次放宽到 5s 就成功了;/status/500 是硬伤,三次之后放弃并记下原因。只重试 ConnectionError / Timeout / 5xx,别重试 404、403;想要更完整的退避,可以用 urllib3.util.retry.Retry 挂到 HTTPAdapter 上。

图片多线程下载

图片防盗链是协议级演示,只能放本机靶站:本机靶站才校验 Referer,而 scrape.center 压根不校验请求头,带不带 Referer 都是 200,演示不出「不带就 403」。本机靶站的图片只认带本站 Referer 的请求,所以顺序是先验 Referer、再落盘。

img_download.py
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
import os
import threading
from concurrent.futures import ThreadPoolExecutor

import requests

BASE = 'http://127.0.0.1:8010'
os.makedirs('imgs', exist_ok=True)
local = threading.local()

def get_session():
if not hasattr(local, 's'):
local.s = requests.Session()
local.s.headers['Referer'] = BASE + '/list' # 设一次,每张图都带上
return local.s

def download(i):
resp = get_session().get(f'{BASE}/img/{i}.png', timeout=10)
resp.raise_for_status() # 先验状态码:403 时 content 是 HTML
path = os.path.join('imgs', f'{i}.png')
with open(path + '.part', 'wb') as f:
for chunk in resp.iter_content(64):
f.write(chunk)
os.replace(path + '.part', path) # 下完才改名,半截文件一眼就能认出来
return path, os.path.getsize(path)

with ThreadPoolExecutor(max_workers=3, thread_name_prefix='img') as ex:
for path, size in ex.map(download, [1, 2, 3]):
print(f' {path} 写了 {size} 字节')
print(f' 残留的半截文件:{[n for n in os.listdir("imgs") if n.endswith(".part")]}')
1
2
3
4
5
6
7
状态码 403
requests.exceptions.HTTPError: 403 Client Error: Forbidden for url: http://127.0.0.1:8010/img/1.png
带 Referer:200,162 字节,Content-Type=image/png
文件头 8 字节:b'\x89PNG\r\n\x1a\n'
imgs\2.png 写了 165 字节
imgs\3.png 写了 165 字节
残留的半截文件:[]
  • 开头那四行是单独用 requests.get 裸跑一张图的实测:不带 Referer 就是 403,而 403 时 r.content 里装的是那段拒绝页 HTML(服务器写的是 <h1>403</h1><p>Referer 校验失败</p>),不是图片;不判状态码就写盘,你会得到一堆打不开的「假图片」。同样的下载写法不带 Referer 跑一遍,三个线程报的都是 HTTPError: 403 Client Error: Forbidden for url: ... 这种。
  • 大文件别整个吞进内存:靶站给 1MB 的文件,实测 stream=False 与 stream=True 各 0.09s 拿到 1048576 字节,3 个文件并发 0.27s;stream=True 配 iter_content() 的好处是内存里永远只有一块。

常见的坑

池不关闭,进程退不出去

  • 解释器退出前会 join 所有非守护线程,而池里的线程默认非守护(实测打出来就是 daemon = False):两个工人还卡在 wait() 时,主线程代码跑完也退不掉,外面 timeout 5 数到点把它杀了,exit=124。补一句 ex.shutdown(wait=False, cancel_futures=True) 也一样退不掉——已经开跑的任务取消不了,cancel_futures 只能取消还没轮到执行的那些。所以 with ThreadPoolExecutor(...) as ex: 只是让作用界清晰,真正能退出靠的是任务本身可停。

Ctrl+C 之后线程不死

ctrl_c_demo.py
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
import os
import subprocess
import sys
import tempfile

CHILD = """
import sys
import threading
import time

stop = threading.Event()

def worker():
while not stop.is_set():
time.sleep(0.2)
print('worker 收到停止信号,准备退出', flush=True)

threading.Thread(target=worker, name='worker').start()
time.sleep(0.8)
try:
raise KeyboardInterrupt # 模拟这一刻按下 Ctrl+C
except KeyboardInterrupt:
print('主线程捕获 KeyboardInterrupt,开始收尾', flush=True)
if sys.argv[1] == 'set':
stop.set()
print('主线程把 stop 事件置上了', flush=True)
else:
print('主线程收尾完了,等着退出', flush=True)
"""

path = os.path.join(tempfile.gettempdir(), 'ctrl_c_child.py')
with open(path, 'w', encoding='utf-8') as f:
f.write(CHILD)

for mode in ('noset', 'set'):
cmd = 'timeout 5 "%s" -X utf8 "%s" %s; echo exit=$?' % (sys.executable, path, mode)
print(subprocess.run(['bash', '-c', cmd], capture_output=True,
text=True, encoding='utf-8', timeout=60).stdout.strip())
1
2
3
4
5
6
7
8
主线程捕获 KeyboardInterrupt,开始收尾
主线程收尾完了,等着退出
exit=124

主线程捕获 KeyboardInterrupt,开始收尾
主线程把 stop 事件置上了
worker 收到停止信号,准备退出
exit=0
  • worker 是 while not stop.is_set(): time.sleep(0.2) 的循环,主线程在 except KeyboardInterrupt 里决定置不置位、它是守护还是非守护,一共跑了三遍:非守护又没有停止信号时,Ctrl+C 只打断主线程,worker 照跑、进程照挂(5s 后被杀掉,exit=124);把 stop 置上、或让 worker 变守护,都能 exit=0。标准做法就两行:全局一个 stop = threading.Event(),每个线程 while not stop.is_set(),except KeyboardInterrupt 里 stop.set() 再 join 收工。

异常、输出与输入

thread_exception.py
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
import subprocess
import sys
from concurrent.futures import ThreadPoolExecutor

CHILD = """
import threading


def boom():
1 / 0


t = threading.Thread(target=boom, name='会炸的线程')
t.start()
t.join()
print('join() 回来了,主线程还以为一切正常')
"""

# 子线程的 traceback 打在子进程的 stderr 上,并进 stdout 才能原样贴出来
p = subprocess.run([sys.executable, '-X', 'utf8', '-c', CHILD],
stdout=subprocess.PIPE, stderr=subprocess.STDOUT,
text=True, encoding='utf-8')
print(p.stdout.rstrip())

with ThreadPoolExecutor(max_workers=1) as ex:
fut = ex.submit(lambda: 1 / 0)
try:
fut.result()
except ZeroDivisionError as e:
print('池里的任务要自己取才看得见:%s: %s' % (type(e).__name__, e))
1

  • 子线程里 1 / 0 出错,只在 stderr 打上面那一段 traceback(中间省略调用它的那一帧),join() 之后主线程什么都不知道,程序照样「成功地」跑完;线程池里 fut.result() 会把异常原样重抛,所以一定要取 result——实战里那句 try: rows.append(fut.result()) 就是在做这件事。
  • 一次 print 是一个整体,四行内容都完整只是顺序随机;拆成两次 sys.stdout.write 就会被劈开,实测看到 A 被拆成两半:B 被拆成两半:C 被拆成两半:D 被拆成两半:DDD CCC BBB AAA。日志要么一条写完,要么用一把锁把整条包起来,或者每个线程写自己的文件、最后合并。
  • 子线程可以用 input(),但 stdin 是所有线程共享的一个流,谁醒着谁抢走:实测 3 个子线程把喂进去的 3 行全抢光,主线程直接 EOFError。所以交互式的「按回车继续」只放主线程,子线程要暂停就等 Event,别等键盘。

怎么选

场景 建议 依据(本机实测)
就抓三五页 单线程 + Session 40 次请求:新建连接 0.50s,复用 0.04s
几十到几百个页面 ThreadPoolExecutor,max_workers 取 4~10 ssr1 抓 30 详情页:单线程 29.97s,5 线程 9.37s(约 3.2x),再加到 10 不涨
下载和解析解耦 Queue + 生产者消费者 设了 maxsize 就自带背压
深度优先追链接 LifoQueue 取出顺序实测 3、2、1
解析很重(大正则、识别) ProcessPoolExecutor 4 段计算:线程 1.52s,进程 0.52s
上千并发、长连接 异步协程 asyncio 线程数与内存都更吃紧
  • 一句话记法:等网络用线程,等 CPU 用进程;想不清楚就先用 with ThreadPoolExecutor(...) as ex: 加 as_completed。线程解决的是「同时等」,不是「更快地算」,真要提速先分清瓶颈在网络上还是在 CPU 上。
  • 配套的坑一次性列在这儿:Session 别跨线程共用、max_workers 不是越大越好、任务要能停、结果回主线程汇总、去重必须一把锁。

参考

本文结束 感谢您的阅读
正在加载今日诗词....